

Premature Optimization — And Its Equally Dangerous Opposite


Premature Optimization — And Its Equally Dangerous Opposite
"Premature optimization is the root of all evil" is probably the most-quoted line in all of programming. It's genuinely good advice — optimizing before you know what's slow wastes effort and adds complexity for nothing. But like all famous advice, it's been twisted into something its author never meant: a blanket excuse to ignore performance entirely, dismiss any efficiency concern as "premature," and write carelessly slow code with a clear conscience. That's not the wisdom — it's the abuse of it.
Here's what the line actually means, and why its opposite is just as dangerous.
Quick Answer
"Premature optimization is evil" is true but widely abused — and the opposite mistake, ignoring performance entirely, is equally dangerous.
The balance:
- Premature optimization is real: optimizing before you know what's slow wastes effort and adds complexity.
- But "don't optimize" is the wrong lesson — it becomes an excuse for careless, slow code.
- The point is timing, not avoidance — optimize when you have data, not on a hunch.
- Reasonable performance awareness is not premature; it's just good engineering.
Measure first, then optimize what matters. Don't optimize blindly — and don't ignore performance entirely.
What the line actually means
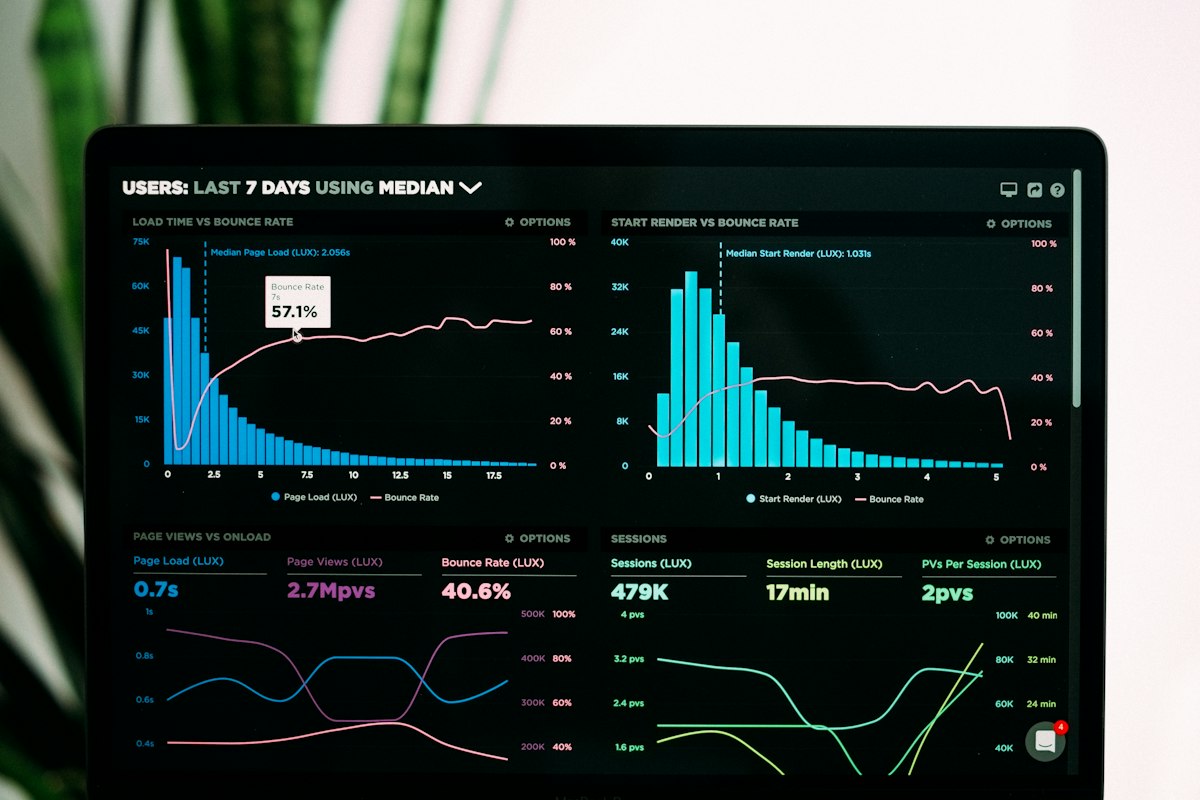
The original wisdom is about timing and evidence, not about avoiding performance work altogether. Premature optimization is dangerous because optimizing before you know what's actually slow means guessing — and performance intuitions are notoriously wrong. You spend effort speeding up code that wasn't a bottleneck, adding complexity that makes the code harder to read and maintain, all to fix a problem you never confirmed existed. The "evil" is optimizing blindly, on a hunch, before you have data telling you where the real cost is.
So the correct reading is: don't optimize until you have evidence about what's slow. Profile, measure, find the actual bottleneck, then optimize that. The vast majority of code isn't performance-critical, and complicating it for imagined speed gains is pure waste. This is genuinely important advice, because the instinct to optimize everything is real and the complexity cost is real. But notice what the advice is actually saying: optimize with data, not never. The target is blind, speculative optimization — not the entire category of performance work.
How the advice gets abused
The abuse comes from dropping the "premature" and hearing only "optimization is evil." Stretched that way, the line becomes a license to ignore performance completely — to write obviously wasteful code, dismiss any efficiency concern as "premature optimization," and treat caring about performance as a beginner's mistake:
| The wisdom | The abuse |
|---|---|
| Don't optimize before you have data | Don't think about performance at all |
| Most code isn't hot — don't complicate it | Write carelessly slow code freely |
| Find the bottleneck, then fix it | Dismiss every perf concern as "premature" |
| Optimize with evidence | Never optimize |
This opposite extreme is just as dangerous, because some performance awareness isn't premature at all — it's just competent engineering. Choosing a reasonable algorithm instead of an obviously quadratic one, not making redundant calls in a loop, picking an appropriate data structure: these aren't "optimizations" to defer until profiling proves a problem. They're baseline good decisions that cost nothing extra to make correctly the first time and are expensive to retrofit later. Using "premature optimization is evil" to justify writing needlessly slow code from the start isn't following the advice — it's hiding carelessness behind a famous quote. The same way technical debt isn't always bad but can't be ignored, performance can't be optimized blindly or ignored entirely.
Finding the middle path
The healthy practice lives between the two extremes, and it's not complicated. Don't optimize blindly — that's premature optimization, real and to be avoided. Don't ignore performance entirely — that's the equally dangerous opposite. Instead: write reasonably efficient code by default (sensible algorithms and data structures, no obvious waste), and when you need to make something genuinely fast, measure first to find the real bottleneck before optimizing.
The distinction that resolves the whole debate is between baseline competence and speculative tuning. Baseline competence — not doing obviously wasteful things — is never premature; it's just doing your job well, and it costs nothing to do right initially. Speculative tuning — restructuring code for performance gains you haven't measured — is what "premature" warns against, and should wait for data. So you don't have to choose between "optimize everything" and "optimize nothing." You write competent code from the start, you stay aware of performance without obsessing, and you reserve real optimization effort for bottlenecks the data has actually identified. Measure first, then optimize what matters — and in the meantime, just don't write careless code. That's the same confidence-through-measurement discipline good engineering applies everywhere: act on evidence, not on hunches in either direction.
How to balance performance and pragmatism
To avoid both premature optimization and its careless opposite:
- Don't optimize on a hunch. Without data on what's slow, optimization is guessing.
- Don't ignore performance either. Careless slow code is the equally dangerous extreme.
- Write competent code by default. Sensible algorithms and structures aren't "premature."
- Measure before tuning. Profile to find the real bottleneck, then optimize that.
- Reserve effort for what matters. Real optimization goes to confirmed hot paths, not imagined ones.
The throughline: "premature optimization is evil" is true but about timing and evidence, not avoidance — and dropping the "premature" turns good advice into an excuse for careless, slow code, which is its own kind of evil. The middle path is simple: write competent code by default, measure before you tune, and optimize the bottlenecks the data actually reveals. Don't optimize blindly; don't ignore performance entirely. Both extremes are mistakes.
The bottom line
"Premature optimization is the root of all evil" is true, but it's about timing and evidence — don't optimize blindly before you know what's slow — not about ignoring performance altogether. Dropping the "premature" turns the wisdom into an excuse for careless, needlessly slow code, and that opposite extreme is just as dangerous, because some performance awareness is simply good engineering rather than premature anything.
The middle path resolves it: write competent code by default — sensible algorithms, no obvious waste, which costs nothing to do right initially — and when something needs to be genuinely fast, measure first to find the real bottleneck, then optimize that. Don't optimize on hunches; don't ignore performance entirely. Act on evidence in both directions, and you avoid both the famous mistake and the careless opposite it's so often used to justify.
The Hidden Costs of Careless Code: Why ‘Just Make It Work’ Backfires
The ‘premature optimization’ backlash often manifests as a ‘just make it work’ mentality, where performance considerations are deferred until a crisis emerges. This approach ignores the compounding costs of careless code. Every redundant database query, nested loop over a large dataset, or unnecessary serialization step might seem trivial in isolation, but they accumulate into systemic latency. The problem isn’t just the immediate slowdown—it’s the technical debt that accrues when these patterns become embedded in the codebase. Refactoring a mature system to replace a naive algorithm with an efficient one often requires rewriting entire modules, retesting edge cases, and coordinating changes across teams. The effort to fix careless code scales non-linearly with time, whereas writing it correctly the first time adds negligible overhead.
Moreover, careless code often hides its true cost behind abstractions. A developer might dismiss a slow API call as ‘not a bottleneck’ during early testing, only to discover later that the same call is made hundreds of times per second in production. By then, the fix requires not just optimizing the call itself, but also reworking the surrounding architecture to batch requests or cache results. The lesson isn’t to obsess over micro-optimizations, but to recognize that ‘making it work’ without any performance awareness is a false economy. Competent engineering means writing code that works and doesn’t introduce obvious waste—no profiling needed to spot a loop that runs in O(n²) when O(n log n) is available.
When ‘Good Enough’ Isn’t: Recognizing the Threshold for Optimization
The line between ‘baseline competence’ and ‘premature optimization’ isn’t always clear, but there are concrete signals that indicate when deeper performance work is justified. The first is scalability: if a component’s runtime grows exponentially with input size (e.g., a nested loop over a growing dataset), it’s not a matter of ‘if’ but ‘when’ it will become a bottleneck. Similarly, predictable latency is a red flag—if a function’s execution time varies wildly based on input, it’s likely doing unnecessary work. Another telltale sign is repetition: code that runs frequently (e.g., in a hot loop, event handler, or background job) deserves closer scrutiny, even if each individual call seems fast. These patterns don’t require profiling to identify; they’re visible in the code itself and should be addressed proactively.
That said, not all performance concerns are equal. Here’s how to prioritize them:
- Obvious waste: Redundant computations, unnecessary allocations, or quadratic algorithms. Fix these immediately—they’re free wins.
- Scalability risks: Code whose runtime grows poorly with input size. Address these before they become problems.
- Hot paths: Frequently executed code (e.g., loops, event handlers). Optimize these only after profiling confirms they’re bottlenecks.
- Cold paths: Rarely executed code (e.g., startup routines, error handlers). Ignore performance here unless profiling proves otherwise.
The key is to distinguish between structural inefficiencies (which should be fixed early) and speculative tuning (which should wait for data). Structural inefficiencies are visible in the code’s design—like a poorly chosen data structure or an algorithm with bad time complexity. Speculative tuning, on the other hand, involves restructuring code for unmeasured gains, like rewriting a function in assembly or manually unrolling loops. The former is just good engineering; the latter is premature optimization.
Performance Culture: How Teams Avoid Both Extremes
A healthy performance culture isn’t about individual discipline—it’s about shared expectations and tools that make the right path the easy path. Teams that avoid both premature optimization and careless code typically adopt a few key practices:
First, they normalize performance awareness by integrating it into code reviews. This doesn’t mean nitpicking every line, but flagging obvious waste (e.g., ‘This loop runs in O(n²)—could we use a hash set here?’) or scalability risks (e.g., ‘This query scans the entire table—can we add an index?’). The goal isn’t to optimize everything, but to prevent careless code from slipping through. Second, they automate performance feedback by adding lightweight checks to CI pipelines. For example, a test that fails if a function’s runtime exceeds a threshold, or a linter that flags known anti-patterns (e.g., N+1 queries). These checks catch regressions early without requiring manual profiling.
Third, they invest in observability to make bottlenecks visible. This means instrumenting code with metrics, logs, and traces, and setting up dashboards to monitor performance in production. When a slowdown occurs, the data reveals the root cause—no guessing required. Finally, they reserve deep optimization for confirmed bottlenecks by adopting a ‘measure-first’ mindset. When a performance issue arises, the team profiles the code, identifies the hot path, and optimizes only that. This ensures effort is spent where it matters, not on imagined problems.
The result is a culture where performance isn’t an afterthought or a source of anxiety, but a routine part of engineering. Developers write competent code by default, flag obvious waste in reviews, and rely on data to guide deeper optimizations. This approach avoids both extremes: it prevents careless code from taking root, while also preventing premature optimization from adding unnecessary complexity. The middle path isn’t a tightrope—it’s the default when performance is treated as a first-class concern, not an afterthought.
Key Takeaways
- Premature optimization wastes effort by guessing bottlenecks—always measure first to identify real performance hotspots before tuning.
- Baseline competence (e.g., avoiding quadratic algorithms, redundant calls, or poor data structures) isn’t ‘premature’—it’s just good engineering with zero extra cost.
- The opposite extreme—ignoring performance entirely—is equally dangerous, leading to carelessly slow code that’s expensive to fix later.
- Reserve deep optimization for confirmed bottlenecks; most code isn’t performance-critical, so speculative tuning adds complexity without benefit.
- The middle path: write non-wasteful code by default, profile to find actual slowdowns, then optimize only what the data proves matters.
- ‘Premature optimization is evil’ is about timing (wait for evidence) and scope (target real bottlenecks), not about avoiding performance work altogether.
Frequently Asked Questions
Does "premature optimization is evil" mean I shouldn't care about performance?
No — that's the abuse of the line, not its meaning. The original wisdom is about timing and evidence: don't optimize before you have data on what's actually slow, because performance intuitions are usually wrong and you'll waste effort adding complexity to fix imagined problems. It targets blind, speculative optimization, not the entire category of performance work. Caring about performance, measuring, and optimizing real bottlenecks is exactly what the advice endorses.
Isn't writing efficient code from the start premature optimization?
Not the baseline kind. There's a difference between baseline competence — choosing a reasonable algorithm, not making redundant calls in a loop, picking an appropriate data structure — and speculative tuning, which restructures code for unmeasured gains. Baseline competence is never premature; it costs nothing extra to do right initially and is expensive to retrofit. Speculative tuning is what "premature" warns against. Don't confuse not-being-wasteful with optimizing — the first is just good engineering.
So when should I actually optimize?
When you have evidence. If something needs to be fast, measure first — profile to find the real bottleneck — then optimize that specific thing, rather than guessing where the cost is. Reserve real optimization effort for confirmed hot paths, not imagined ones, since most code isn't performance-critical and complicating it for speculative gains is waste. In the meantime, write competent, non-wasteful code by default. Measure first, optimize what matters, and don't be careless in either direction.



Comments
Sign in to join the conversation
No comments yet. Be the first to share your thoughts!